Open Source
LocalAI
Make AI run on every machine
- 0community votes
- 69DR by Ahrefs +1 (up) since last check
- 2023founded
Ahrefs Domain Rating signal 18 Nov 2026, signal shifted 4 Nov 2026.
Open source AI engine that runs language models, vision, voice, image and video workloads on any hardware without GPU requirements.
What it is
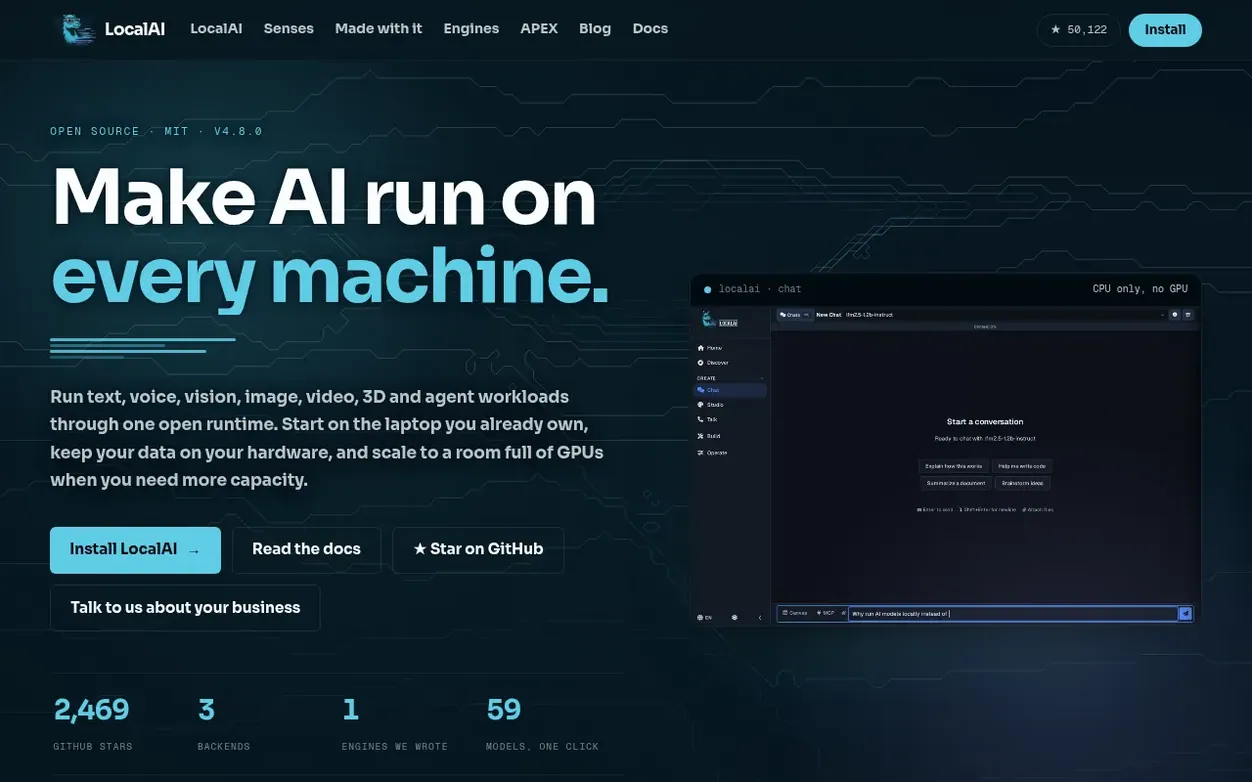
LocalAI is an open source runtime that lets you run text, voice, vision, image, video, 3D and agent workloads through a single interface. Start on a laptop you already own, keep your data on your hardware, and scale to multiple machines when needed.
The runtime provides a drop-in replacement for OpenAI, Anthropic, Ollama and ElevenLabs APIs. One binary includes multiple swappable backends—a model can run on llama.cpp, vLLM, SGLang or MLX without the client noticing. The core only pulls in the engines a model requests, keeping the base install small.
Every feature ships with a CPU path first, tested on hardware most people own. GPU acceleration is optional. The project supports x86_64, ARM64, CUDA, ROCm, SYCL, Metal and Vulkan across devices from Raspberry Pi to clusters.
LocalAI includes speech recognition and synthesis, vision capabilities for detection and 3D reconstruction, image and video generation, agent orchestration with MCP support, and distributed clustering with VRAM-aware routing and failover handling.
Systems
- OpenAI API compatibility
- Swappable backends
- Real-time voice in and out
- Vision and spatial understanding
- Distributed clustering
- Agent orchestration
- Privacy filtering
- Built-in agent with MCP support
Pricing
Pricing model: Free
Want to see what LocalAI does next? Follow them for milestones, new products and stories by email.
LocalAI metrics
Signal readout for localai.io: Ahrefs Domain Rating and Majestic link signals, arrows for the change since the last scan.
- 69 Domain Rating +1 (up) since last check
- 28 Trust Flow no change since last check
- 46 Citation Flow no change since last check
- 1,943 Referring domains no change since last check
- 17,752 External backlinks no change since last check
Ahrefs Domain Rating signal 18 Nov 2026, signal shifted 4 Nov 2026. Strongest signal topic: Computers/Security (27). Majestic signal 3 Oct 2026, signal shifted 3 Oct 2026. Link signals from Majestic. Trust Flow, Citation Flow and Topical Trust Flow are trademarks of Majestic-12 Ltd.
LocalAI domain signal
Show the signal details
Public RDAP record, last read 17 Nov 2026, 02:08 UTC.
- Domain age 3 years
- Registered
- Expires
- Registrar Cloudflare, Inc
- DNSSEC Not signed
LocalAI post-launch signal
The record for LocalAI after its launch on Nexora Launch (3 October 2026), from the readings we keep.
- 69 Domain Rating (Ahrefs) +2 (up) since launch
at launch: 67 (3 Oct 2026); latest: 17 Nov 2026 - 28 Trust Flow (Majestic)
first measured 3 Oct 2026 - 1,943 Referring domains (Majestic)
first measured 3 Oct 2026
Checkpoints
- Day 302 Nov 2026DR 68 +1 (up) since launch0 visits sent
Day 45 since launch. Next receipt: day 60, 2 Dec 2026. A change here is a reading, not a claim about its cause; lots of things move these figures. Anything we do not measure is not shown.
Got a launch coming up?
Plan your launch with our free playbook, from preparing your listing to choosing more launch directories.
Quick answers
- What APIs does LocalAI support?
- LocalAI speaks the OpenAI, Anthropic, Ollama and ElevenLabs APIs. Most tools need only a URL change and nothing else to point at LocalAI instead of the cloud service.
- How does model selection and engine switching work?
- The engine behind the API is swappable. One model can run on llama.cpp while the next loads on vLLM, SGLang or MLX, and the client never notices the difference. Switching is one line in the model's config.
- Does LocalAI require a GPU?
- No. Every feature ships a CPU path first that is tested in CI on the hardware most people already have. A GPU makes it faster but is not required.
- How does distributed clustering work in LocalAI?
- When you add a second machine, it reports what hardware it has and which backends it can run, then joins the pool. Requests land on the replica that already holds the model and the matching prefix cache, and if a node fails, in-flight work reschedules automatically.
- What is APEX quantization?
- APEX assigns a different precision to every tensor and every layer, allowing large models to fit on consumer GPUs with faster inference. A 35B mixture-of-experts model goes from 64.6 GB at 30.4 tokens per second to 12.2 GB at 74.4 tokens per second, with minimal quality loss.
LocalAI has a free listing. The owner can unlock the full profile with a paid launch for $5:
- Founder story (locked)
- Milestones (locked)
- Demo video (locked)
- Dofollow website link: not on this free listing (its website link is nofollow)
Also on the frontier
-
 DR 75 −1 (down) since last check 0 votes. Log in to send Nomic a vote
-
DR 72 +1 (up) since last check 0 votes. Log in to send Jan a vote
-
DR 79 no change since last check 0 votes. Log in to send MLflow a vote
-
Rank 4: Ollama
An API for open models. Get inference locally or in the cloud, anywhere you already work.
DR 89 +1 (up) since last check 0 votes. Log in to send Ollama a vote