
AI inference & GPU cloud
BitsRun
Deploy any open model from Ollama or Hugging Face as a private, OpenAI-compatible API
- 0community votes
- 0DR by Ahrefs no change since last check
Ahrefs Domain Rating signal 13 Nov 2026, signal shifted 13 Nov 2026.
BitsRun turns any open model from Ollama or Hugging Face into your own private API that scales to zero, charged per second only while running.
What it is
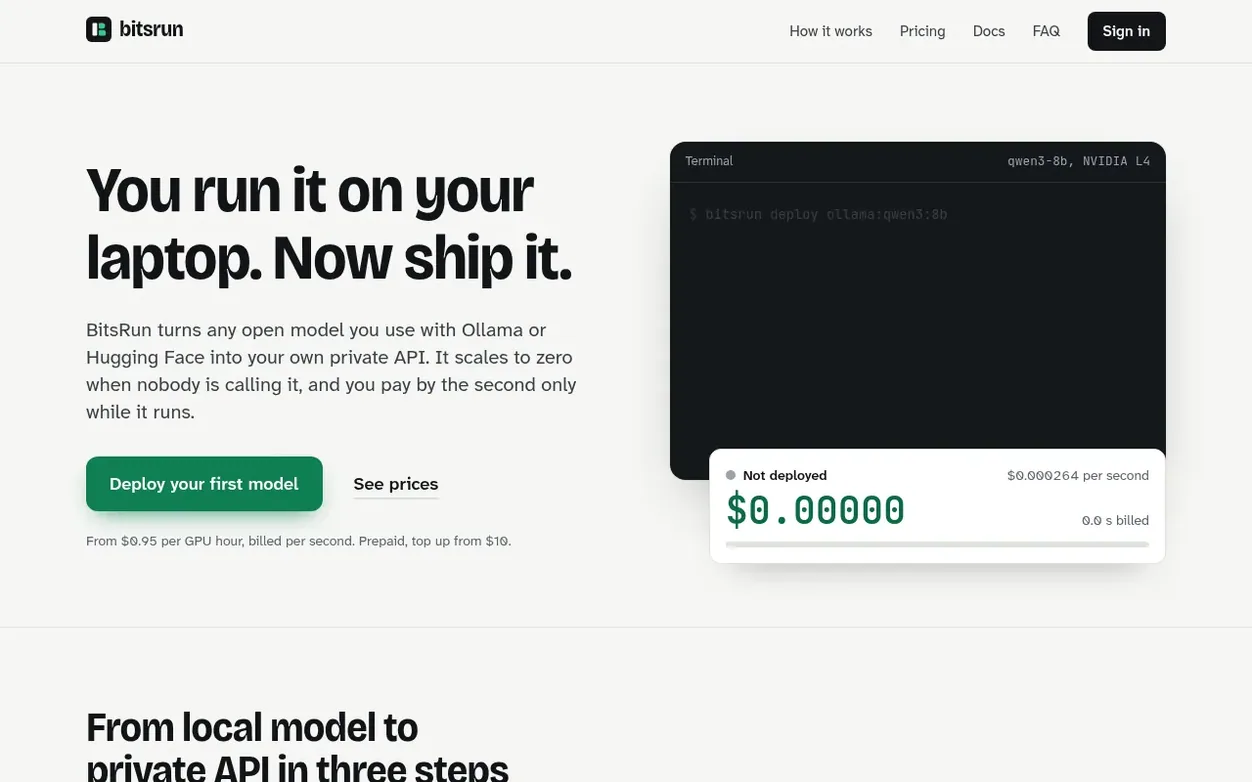
BitsRun lets you deploy any open AI model you already use with Ollama or Hugging Face as a private API endpoint. You choose the model, deploy it with one command, and call it from your app using the OpenAI or Ollama client you already have by changing only the base URL. The service scales to zero when no one is calling it, and you pay per second only while your model is running, with pricing starting from $0.95 per GPU hour for an NVIDIA L4 with 24GB memory. You prepay for credits starting at $10 and can set a monthly cap to avoid surprise bills. The service supports large language models in GGUF or safetensors formats, plus embedding and reranking models, running on managed systems in the United States.
Systems
- Deploy models with one command via CLI
- OpenAI and Ollama API compatibility
- Scales to zero with configurable idle timeout (60 seconds to 60 minutes)
- Private endpoints with no prompt logging
- Supports GGUF and safetensors model formats
- Free model storage (10GB to 1TB depending on plan)
- Always-on option for no cold starts
- Batch jobs pricing 30-50% cheaper
Pricing
Pricing model: Paid
Pay as you go: $0/month with prepaid credits from $10. Pro: $29/month with $29 monthly credits. Business: $299/month with $299 monthly credits. GPU pricing: NVIDIA L4 $0.95/hour ($0.000264/second, $1,180/month always-on); NVIDIA L40S $3.20/hour ($0.000889/second, $3,974/month always-on); 4x NVIDIA L
Want to see what BitsRun does next? Follow them for milestones, new products and stories by email.
BitsRun metrics
Signal readout for bitsrun.com: Ahrefs Domain Rating and Majestic link signals, arrows for the change since the last scan.
- 0 Domain Rating no change since last check
- 0 Trust Flow no change since last check
- 0 Citation Flow no change since last check
- 0 Referring domains no change since last check
- 0 External backlinks no change since last check
Ahrefs Domain Rating signal 13 Nov 2026, signal shifted 13 Nov 2026. Majestic signal 13 Nov 2026, signal shifted 13 Nov 2026. Link signals from Majestic. Trust Flow, Citation Flow and Topical Trust Flow are trademarks of Majestic-12 Ltd.
BitsRun domain signal
Show the signal details
Public RDAP record, last read 13 Nov 2026, 15:50 UTC.
- Domain age 12 days
- Registered
- Expires
- Registrar Amazon Registrar, Inc.
- DNSSEC Not signed
Got a launch coming up?
Plan your launch with our free playbook, from preparing your listing to choosing more launch directories.
Quick answers
- Which models can I run?
- Large language models in GGUF through llama.cpp or safetensors through vLLM, plus embedding and reranking models. Image and audio models are on the roadmap.
- How long does a cold start take?
- On a warm GPU, a model is usually ready in a few seconds to about 40 seconds. When a new GPU has to start, GGUF and embedding models take about 2 to 3 minutes, and safetensors models about 3 to 4 minutes. None of that time is billed.
- What does the idle timeout do?
- The idle timeout determines how long your endpoint stays up after the last request, so the next request answers instantly. You can choose from 60 seconds to 60 minutes and you pay per second while it waits.
- Can I keep an endpoint always on?
- Yes. You can turn on always-on mode and your endpoint keeps a dedicated GPU that never sleeps, eliminating cold starts. It is billed by the second while on at a monthly rate, such as $1,180 per month for an L4.
- Do I need a GPU or Docker?
- No. If the model runs in Ollama or loads from Hugging Face, BitsRun can serve it. You never write a Dockerfile.
BitsRun has a free listing. The owner can unlock the full profile with a paid launch for $5:
- Founder story (locked)
- Milestones (locked)
- Demo video (locked)
- Dofollow website link (locked)
Also on the frontier
-
 DR 0 no change since last check 0 votes. Log in to send Anona Compute a vote
-

Rank 2: Dory
Persistent Linux computers for AI agents, from about $0.03 an hour
DR 0 no change since last check 0 votes. Log in to send Dory a vote -
 DR 12 +2 (up) since last check 0 votes. Log in to send condense a vote
-
Rank 4: Tenki
Cloud infrastructure for your code and agents
AI inference & GPU cloudStartupUnited States
DR 47 no change since last check 0 votes. Log in to send Tenki a vote