Transform photos into personalized cartoon characters with AI
Open-source SDXL-based AI model for native high-resolution anime art generation
Stage
Not given
Not given
Founded
Not given
Not given
Based in
Not given
Not given
Pricing model
Freemium
Open source
Pricing
Free: 5 credits included with new account. Mini: $6.90 for 30 credits (about 10 memojis). Starter: $9.90 for 60 credits (about 20 memojis). Plus: $19.90 for 150 credits (about 50 memojis). Max: $29.90 for 600 credits (about 200 memojis). All packs are one-time purchases with no expiration.
Free for personal and research use; prohibits closed-source proprietary monetization
Key features
Convert photos to Apple iOS-style memoji characters in seconds
Multiple character styles: memoji, 3D cartoon, chibi sticker, and clay figure
Custom expressions via text instructions before generation
HD quality output on pastel studio background
Supports JPG, PNG, and WebP photos up to 20 MB
One-step generation with no editor or slider adjustments
Fast generation, most complete while you wait
Commercial use rights for all generated memojis
Privacy-first design with automatic photo deletion
Automatic refund of credits if generation fails
Native 1536x1536 high-resolution generation without upscaling
Hybrid Prompting System combining natural English and Danbooru tags
Stable text encoder fine-tuning for superior concept understanding
Trained on comprehensive Danbooru2023 dataset
Full compatibility with ComfyUI, Automatic1111, Forge, and Draw Things
Superior anatomy rendering with flawless hands and character details
V-Prediction architecture for enhanced dynamic range and contrast
Highly flexible base canvas for LoRA training and custom checkpoints
What makes it different
No subscription required - pay per use with credits that never expire
Privacy-focused with photos deleted and never used for model training
Fast single-step generation with no editing required
Full commercial rights included for all generated content
Multiple artistic styles beyond standard memoji design
Only open-source SDXL model natively trained at 1536x1536 resolution
Stylistically neutral untuned base canvas unlike Pony Diffusion
Continuous rapid iterations from v0.1 to v3.5 with aggressive optimization
Thousands of compatible community-trained LoRAs and derivatives
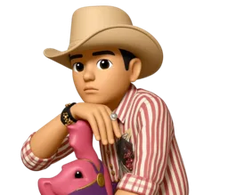 Memoji Generator
 Illustrious XL